

What Practices Are Beneficial for Training AI Models with Prompts
Most people use the word “training” loosely when they talk about prompts. You write a prompt, the answer improves, and it feels like the model learned something. In a narrow sense it didn’t — a prompt doesn’t change the model’s weights. But in the practical sense that matters day to day, you absolutely are training it. You are shaping its behavior for your task, your audience, and your standards, one instruction at a time.
The practices below consistently make that shaping work. They help whether you’re steering a model in a chat window, building prompts into a product, or preparing prompt-formatted examples for fine-tuning. None of them are tricks; they’re habits. And the difference between people who get reliable output and people who keep re-rolling the dice is almost always these habits, not clever wording.
First, a Quick Clarification
Prompting means guiding a model at the moment you use it. The instructions, examples, and context live inside your request, and the model’s underlying parameters never change. This is sometimes called in-context learning — the model “learns” your pattern from the context you give it, then forgets it when the session ends.
Training with prompts, in the stricter sense, means using prompts as data. Teams collect prompt-and-response pairs for supervised fine-tuning or preference training, which does update the model. The quality bar is higher there, because a bad example doesn’t just ruin one answer — it gets baked into behavior for every future user.
Here’s the useful part: the same core practices serve both. Clear instructions, good examples, structured context, and honest evaluation improve a one-off prompt and a training dataset alike. It also helps to pick work the model is genuinely suited to, so before blaming a prompt, think through what would be an appropriate task for using generative AI.
Start With a Clear Instruction and a Defined Role
A vague prompt forces the model to guess which of a thousand plausible answers you wanted. “Write about onboarding” could mean a blog post, an email sequence, a checklist, or a training manual. The model will pick the most average option, which is rarely what you need.
A strong instruction answers four questions up front: what is the task, stated with a specific verb (summarize, classify, extract, rewrite)? Who is the output for, and what will they do with it? What does good look like — length, tone, the one or two things that matter most? And what role should the model take? A role like “you are a support lead who writes calm, plain-language replies” narrows the model’s choices in a useful way. It activates a consistent style and level of expertise instead of a generic one. Above all, replace fuzzy goals (“make this better”) with observable ones (“shorten this to under 100 words, keep every date and figure, remove the adjectives”) — if you can’t describe the result in one concrete sentence, you’re still deciding what the task is.
Show the Model What Good Looks Like With Few-Shot Examples
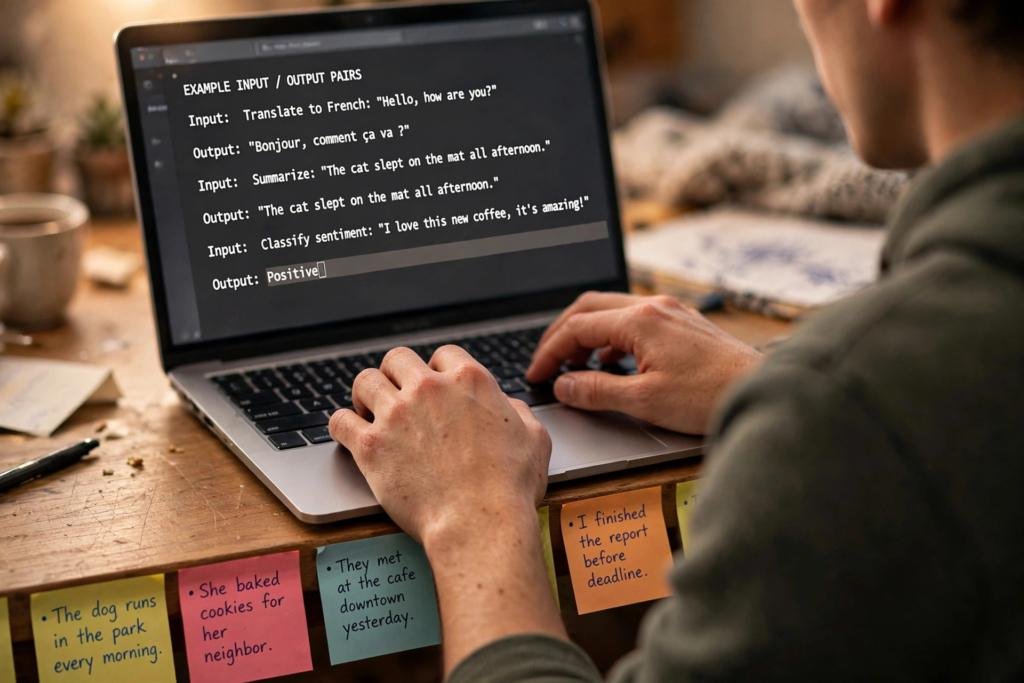
Instructions describe; examples demonstrate — and models are far better at following a demonstrated pattern than an abstract description of one. Giving two to five input-and-output pairs is called few-shot prompting, and it’s the closest thing to hands-on training you can do inside a single request. Here’s what it looks like on a common task, tagging support tickets.
Weak prompt:
Tag this support ticket with a category.
Improved prompt:
You are tagging support tickets for a small online store. Read each ticket and reply with exactly one category from this list: Shipping, Billing, Product Issue, Account, Other.
Ticket: “My parcel says delivered but nothing arrived.”
Category: ShippingTicket: “I was charged twice for the same order.”
Category: BillingTicket: “The app logs me out every time I open it.”
Category: Product IssueTicket: “Where is my refund? It has been nine days.”
Category:
Notice what the examples did that instructions alone couldn’t. They fixed the output format: one word, nothing else. They also showed how a refund question belongs to Billing rather than Shipping even though it mentions an order. Those are boundary cases, taught by demonstration. When you build your own sets, include at least one hard case. Try the ambiguous ticket, or the near-miss that almost belongs in another category. Sets of only easy examples teach the model a tidier world than the one your real inputs live in — and keep examples consistent, because two near-identical inputs labeled differently teach noise, not judgment.
Structure the Prompt and Keep Instructions Separate From Data
As prompts grow, a single wall of text becomes unreliable: the model drops a requirement buried in the middle, or mistakes something inside the material you pasted for an instruction it should follow. The fix is boring and effective — give the prompt labeled sections:
- Task — what to do, in a sentence or two.
- Context — audience, purpose, relevant facts.
- Data — the material to work on, fenced off with headings, quotes, or tags.
- Constraints — the rules and limits.
- Output format — the exact shape of the answer.
That separation matters even more once prompts drive automated systems, where each step’s output becomes the next step’s input. A muddled instruction compounds fast there — the foundation that what is agentic AI builds on. One more structural habit: put your most important requirement near the end, because in long prompts models tend to weight the final instructions heavily.
Add Context, Constraints, and the Reason Behind Them
Constraints are where prompts quietly succeed or fail. Positive constraints define the boundaries of the answer: word limits, required sections, reading level, what must be included. Negative instructions name what must not appear: no invented figures, no recommendations when you only asked for a summary, no bullet points in a formal letter. Negative instructions work best when they name a specific failure you’ve actually seen, not a vague quality like “avoid being bad.”
And here’s a detail many guides skip: explain why a constraint exists, because a bare rule generalizes poorly. Compare:
Weak prompt:
Summarize this incident report. Keep it short. No jargon.
Improved prompt:
You are summarizing an incident report for a non-technical manager who must decide whether to escalate it. Write three short paragraphs, under 150 words total. Use plain language, because the reader has no engineering background — if a technical term is unavoidable, define it in a few words the first time it appears. Keep every date, name, and figure from the original exactly as written, and do not add causes or conclusions the report itself doesn’t state.
The improved version doesn’t just add rules. It gives the model the reasoning behind them, so it can handle cases you didn’t think to list. “The reader must decide whether to escalate” quietly tells the model to surface impact and urgency: the difference between a rule and an understanding.
Refine in Small Steps and Version Every Prompt
The fastest way to ruin a decent prompt is to rewrite five things at once — when the output changes, you won’t know which edit helped, which hurt, and which did nothing. Instead, change one thing at a time, re-run the same inputs, and keep a simple version history. Even a dated note like “v3: added billing example, fixed refund mislabels” is enough. It just needs to record what you were trying to fix, not just what you changed. It sounds like overhead — until a model update shifts your outputs and the log is the only way to tell whether the prompt or the model moved.
Test Against a Fixed Evaluation Set With a Simple Rubric
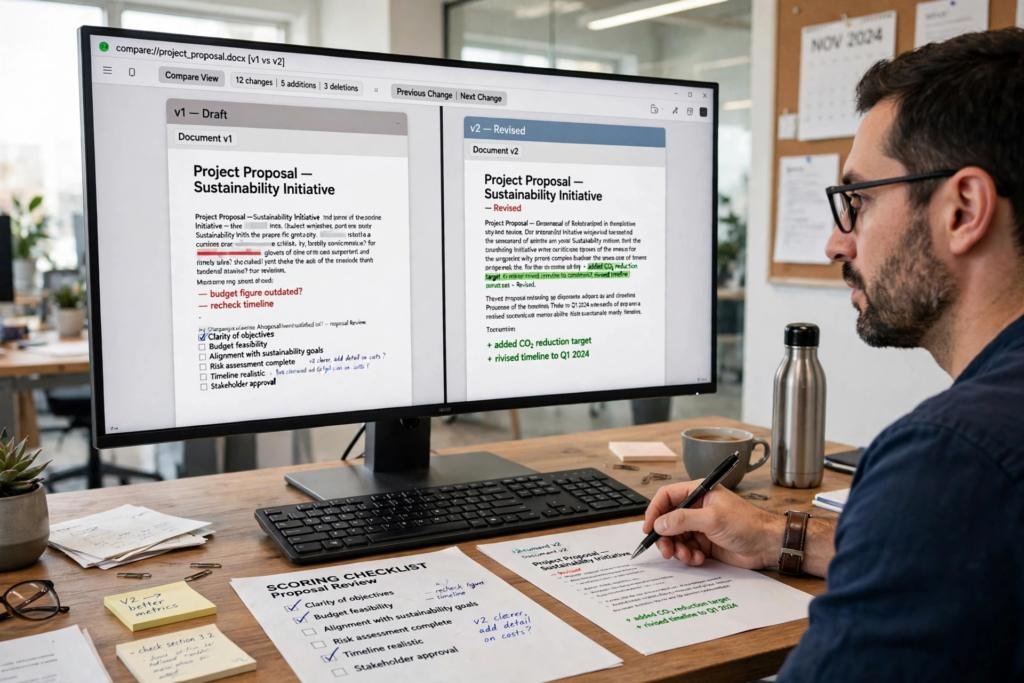
Most prompt “testing” is really just vibes — run it twice, read the answers, feel good. The problem is that a prompt can shine on the examples you wrote it from. It can still fail on the third real input it ever sees. A lightweight evaluation habit fixes this, with no special tooling:
- Collect 10 to 20 real inputs — actual tickets, documents, or questions from your work, including a few messy ones. Freeze the set; don’t edit it to flatter the results.
- Write a short rubric before scoring anything. Four criteria scored from 1 to 5 are plenty for most tasks:
| Criterion | What a 5 looks like | What a 1 looks like |
|---|---|---|
| Accuracy | Every fact matches the source | Facts invented or altered |
| Format fit | Output matches the requested shape exactly | Right content, unusable shape |
| Instruction following | All constraints respected | Key constraints ignored |
| Usefulness | Ready to use with little or no editing | Needs a full rewrite |
- Score each prompt version against the same frozen set, recording the scores next to the version number.
- Keep the hard cases visible. Averages hide the failures that matter, so check the worst three outputs separately before declaring a version better.
The same discipline scales to evaluating whole systems of cooperating models, as explored in how to improve AI agent performance in sovereign multi-agent systems.
Keep Settings Consistent and Test Across Models
A prompt doesn’t run in a vacuum. Generation settings change the output as surely as wording does. Temperature is the key one: it controls how much randomness the model uses. So use low temperature for extraction, classification, and anything factual, where you want the most predictable answer every time, and higher temperature sparingly, for brainstorming or early drafts where variety is the point. Hold settings constant while you compare prompt versions — if the temperature changed too, your evaluation measured two things at once and taught you nothing. And re-test when you switch models, because wording tuned tightly to one model often drifts on another. The thread running through all of this is simple: change one variable at a time, whether it’s a sentence, a setting, or the model itself.
Turn Winning Prompts Into a Small, Documented Library
The last practice is the one that compounds. When a prompt works, don’t leave it buried in a chat history. Save it as a reusable template with a few lines of documentation. Note its name and purpose in one line. Include the prompt itself, with the variable parts clearly marked (the text to summarize, the ticket to tag). Record where it was tested — model, settings, and its score on your evaluation set. And note its known limits, so the next person isn’t surprised by the inputs it handles badly.
A dozen documented prompts like this are worth more than a hundred forgotten chats. They’re exactly the raw material you’d want if you later fine-tuned a model on your own examples. They are consistent, structured, and already quality-checked. Before reusing one, run this quick check. Is the task stated in one observable sentence? Do you have two to five consistent examples, including a hard one? Are instructions and data in separate, labeled blocks? Are constraints specific, with reasons where it matters? Is there a frozen test set and a score for this version? Five yeses, and the prompt is trained about as well as a prompt can be.
Frequently Asked Questions
Not in the technical sense — a prompt doesn’t change the model’s weights, and its effect ends with your session. It steers behavior through in-context learning, which feels like training because the output improves. Permanent changes require fine-tuning or preference training built on prompt-formatted data.
Two to five examples is the reliable range for most tasks. One rarely establishes a clear pattern, and beyond five the returns shrink while the prompt gets harder to maintain. Diversity matters more than quantity — include one genuinely hard or ambiguous case rather than five easy ones.
Zero-shot means an instruction with no examples — you rely on the model’s general training. Few-shot adds a few worked input-and-output pairs before the real input, which usually improves format consistency and edge-case handling because the model can pattern-match instead of guessing what you meant.
Use it for multi-step problems — math, logic, planning, anything where an early mistake poisons the final answer. Ask the model to work through the steps before answering. Keep it bounded, though: cap the steps or length, because open-ended reasoning can ramble and adds little on simple tasks or on models that already reason internally.
Run both versions against the same frozen set of real inputs and score them with a rubric you wrote in advance — accuracy, format fit, instruction following, and usefulness work well. Testing only on the examples that inspired the change just measures how well the prompt fits its own homework.
Start with better prompts — they’re faster, cheaper, and reversible, and they fix most problems. Consider fine-tuning when the task is stable and high-volume, you have a solid set of quality-checked examples, and prompting alone can’t deliver the consistency you need.

Hamad Arshad writes and edits AI Next Top from Rahim Yar Khan, Pakistan. He has worked in SEO and digital marketing for over 7 years and started this site to explain AI tools and news in plain language for non-technical readers. Every guide here is checked against the real tool before it is published.

Leave a Reply