
How Do LLMs Work
You type a question into a chatbot, and seconds later it answers in full, friendly sentences, almost like a person typing back at you. It feels like magic — until the same tool confidently tells you something that turns out to be completely wrong.
Beneath the chat window sits a large language model, or LLM, which is software built on what is a neural network at huge scale. An LLM does one thing, over and over. It predicts text. Everything else — essays, code, jokes, homework help — is built on that trick.
In short: An LLM is a program trained on enormous amounts of text. It chops text into tokens, learns the patterns between them, and writes by predicting the most likely next token, one piece at a time. It does not look answers up, and it does not truly understand them — which is why it can sound brilliant one moment and confidently wrong the next.
What an LLM actually is
The name gives away most of the story. A language model learns how words and sentences usually fit together. Large means it was trained on a huge amount of text and has billions of internal settings. Put together, it is software that has absorbed the patterns of written language deeply enough to continue almost any text.
LLMs are one branch of the different types of ai, alongside systems that recognise faces, recommend videos, or steer warehouse robots. Those systems do narrow jobs. The LLM’s one job, predicting text, turns out to be surprisingly general. Text can describe almost anything, so a model that handles text well can help with almost anything.
An LLM is not a database, either. It stores no web pages, and the training text is long gone. What remains is its pattern, compressed into numbers.
First, the text gets chopped into tokens
Computers do not read words the way you do. Before an LLM can work with text, the text is split into small chunks called tokens. A token might be a whole short word like “cat”, part of a longer word like “ing”, or a single punctuation mark.
Roughly, a thousand tokens is about 750 words of ordinary English. Your question becomes tokens, and the answer is produced as tokens too, then stitched back into readable text.
Because the model works with chunks rather than letters, it can stumble on oddly specific things, like counting the letters in a word.
Trained on more text than anyone could read
Before an LLM can predict anything useful, it goes through training, reading staggering amounts of text from books, articles, websites, and documentation. No human team labels all of this by hand. The model teaches itself with a simple game it plays billions upon billions of times.
The game is simple. Take a real sentence, hide the next token. The model guesses what comes next. The answer is revealed, and its internal settings are nudged a tiny fraction in whichever direction would have made the guess better. Repeat, across more text than any person could read in a thousand lifetimes.
That is all training really is — guessing, checking, adjusting, at a scale that makes it extraordinary. By the end, it has absorbed grammar, facts, writing styles, and common reasoning patterns. It has not memorised the library. It has absorbed the shape of the library.
The one trick behind everything
After training, the machine does one thing remarkably well. Given some text, it calculates which token is most likely to come next — not the one correct token, but a ranked list of probabilities. After “The capital of France is”, “Paris” scores very high, a few other city names score low, and “banana” scores almost nothing.
When you chat with an LLM, it generates its answer one token at a time. It predicts a token, adds it to the text, then predicts the next from everything so far, including its own words. That loop, repeated hundreds of times, is how a full answer appears word by word — and why the same question can get a slightly different answer each time. The model samples from its top choices rather than always picking the single most likely one, keeping answers natural instead of robotic.
Think of it as the world’s most well-read improviser, making things up on the spot, in character, guided by everything it has read. Sometimes the improvisation is superb. Sometimes it wanders off a cliff — more on that shortly.
Transformers and attention in plain words
Modern LLMs are built on an architecture called the transformer. One part of it deserves your attention, because it happens to be called attention.
When you read “The trophy does not fit in the suitcase because it is too big”, you instantly know “it” means the trophy. Attention is the mechanism that lets a model do something similar. As it processes each token, it weighs which earlier tokens matter most — who did what, what a pronoun points back to, and which detail from three sentences ago matters now.
Older designs read text one word at a time, constantly forgetting the beginning. Transformers look at the whole passage at once and decide what deserves focus. That shift is a big reason LLMs can handle long documents, follow complicated instructions, and hold a coherent conversation.
Parameters, the billions of tiny dials
If tokens are the model’s raw material, parameters are its memory of patterns. A parameter is simply a number, one tiny adjustable setting inside the network, and training is the long process of tuning those numbers. That means billions of little dials, each nudged into place by all that guessing and checking.
When people call one model bigger than another, this is what they mean. More parameters generally let a model capture finer patterns and more knowledge, which is part of why anyone comparing tools while hunting for the best chatgpt model notices real quality differences between versions. Bigger is not automatically better, though — training and refinement matter just as much as the raw count.
Those dials are not a neat filing cabinet of facts, either. Knowledge in an LLM is smeared across all the numbers at once, like flavour in a soup rather than ingredients on a shelf. Nobody can point to exactly where a particular fact lives.
Fine-tuning, where a raw model learns manners
A freshly trained LLM is not yet the polite assistant you meet in a chat window. Left alone, it simply continues text. Ask it a question and it might cheerfully continue with more questions, because questions often follow questions in its training data.
So developers refine it. In fine-tuning, the model is trained further on examples of good conversations, helpful answers, and safe behaviour. Human reviewers often rank sample answers, and the model is adjusted to favour the kind of answers people preferred. This stage is much smaller than the original training, but it changes the personality completely — from a machine that continues text to an assistant that answers questions and follows instructions.
Only then is it wrapped in the app you use, sometimes with extras like web search or code tools. The same idea powers daily automation, as shown in How AI Agents Can Automate Your Daily Work.
How an LLM differs from a rules-based chatbot
| Question | Rules-based chatbot | LLM |
|---|---|---|
| How does it answer | Picks from replies written in advance | Builds a fresh answer, token by token |
| What can it handle | Only the topics it was scripted for | Almost any topic expressed in words |
| How does it fail | Says it does not understand | Sometimes answers confidently and wrongly |
The old bot failed by going silent. The new one can fail by sounding wonderful while being wrong.
Why LLMs sometimes make things up
Every so often, an LLM states a falsehood with total confidence — an invented book, a law never passed, a wrong date. This behaviour is often called hallucination, and once you understand the machinery, it stops being mysterious.
The model was trained to predict text that fits the pattern, never to check whether a statement is true. Plausible and true usually overlap, because its training text was mostly accurate. But at the edge of what it knows, the model feels no edge. It keeps improvising, because fluent text is the only job it has. So treat its answers like a smart, overconfident colleague — great for a first draft, never the final word on anything that matters.
What LLMs power in everyday life
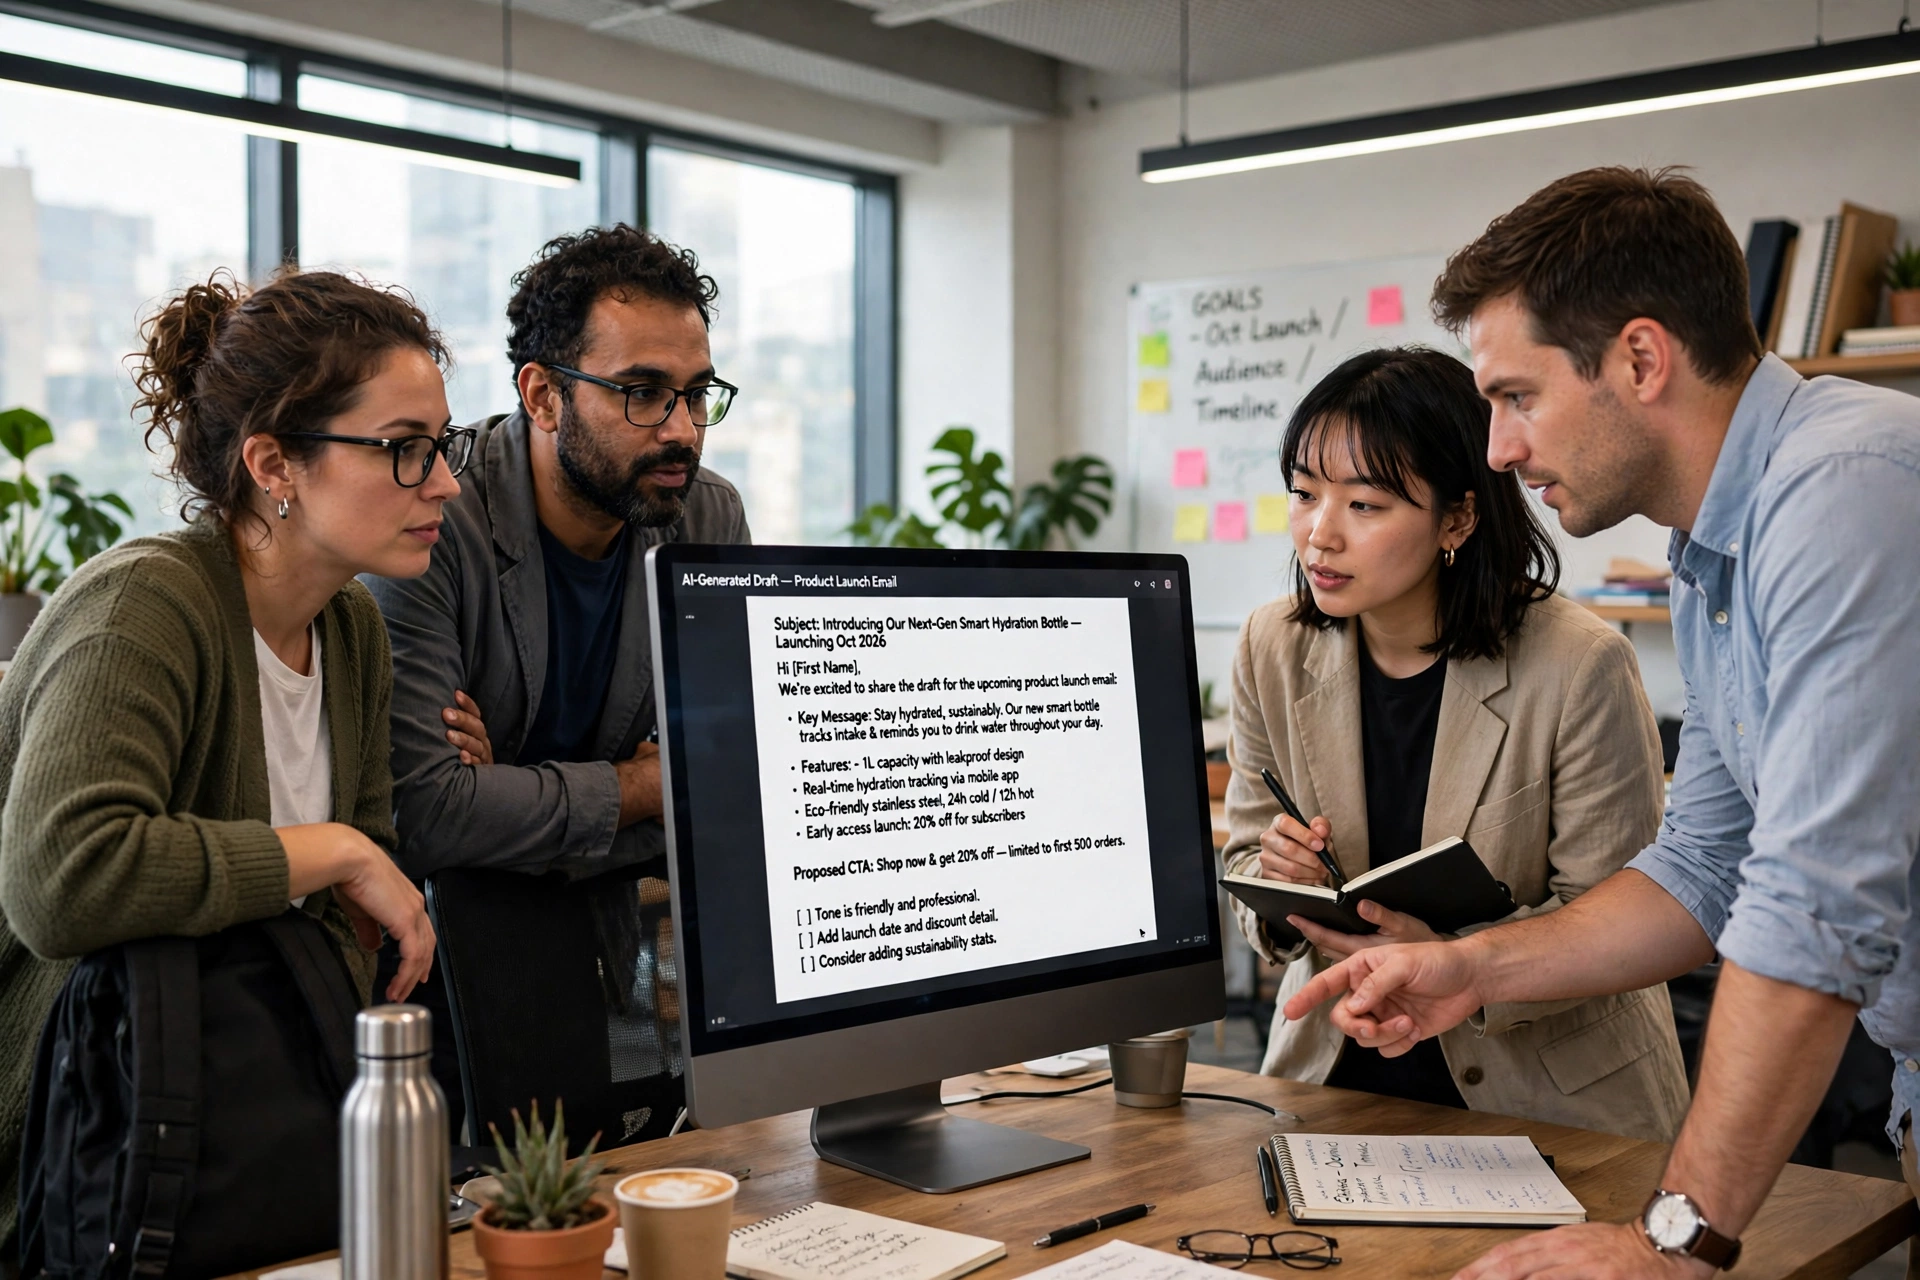
The same engine powers far more than chat windows. LLMs draft emails, summarise documents and meeting notes, help programmers debug code, answer customer questions, translate languages, and explain topics to students at any level. Search engines use them for those neat summary paragraphs, too. For affordable options, see Cheapest AI Tools in 2026 That Actually Work. For meetings, see Does Granola AI Work for In-Person Meetings?
None of this needs the model to be conscious or wise — just good at language. That is the everyday purpose of ai in these tools. Not replacing human judgement, but taking on the heavy lifting of reading, drafting, and rephrasing, so people can spend their attention where it is actually needed.
The honest limits of LLMs
A clear picture should include where the machinery runs out.
- No real understanding. Brilliant with patterns in text, but that is not the same as knowing what words mean.
- A frozen education. Its knowledge stops when training ends, unless the product adds live search.
- Confident by default. It rarely sounds unsure, even when it should, so check anything important.
- Echoes of its training. Biases and errors in its training text can surface in its answers.
- Shaky on precision. Exact maths, long logic chains, and counting are weak spots, because prediction is not calculation.
Tools work best when you know their shape. Looking ahead, multi-agent systems are central to Multi-Agent AI Systems: The Future of Work in 2026. The future of work is also at stake in Geoffrey Hinton and the AI Jobs Crisis: What His Warnings Mean for the Future of Work.
Frequently asked questions
Large language model. Large describes its scale, language is what it works with, and a model is simply a system that learns patterns from data instead of following fixed rules.
No. An LLM is one kind of AI, specialised in language. The wider field also includes systems that recognise images, recommend content, and translate speech.
Not in the human sense. It has no experiences or beliefs — just extraordinarily good pattern matching. Its answers can be accurate and useful, but they do not come from understanding.
Generation involves a little randomness. The model samples from its most likely next tokens instead of always choosing the top one, so two runs can wander down slightly different paths.
Not during your chat — the model itself stays frozen, though it uses your conversation as context, which feels like memory. Whether chats train future versions depends on the product’s privacy settings.
A search engine finds existing pages and points you to them. An LLM generates a fresh answer in its own words. One gives you sources to check; the other gives you an answer to check.

Hamad Arshad writes and edits AI Next Top from Rahim Yar Khan, Pakistan. He has worked in SEO and digital marketing for over 7 years and started this site to explain AI tools and news in plain language for non-technical readers. Every guide here is checked against the real tool before it is published.
Leave a Reply